How to Make a Scanned PDF Searchable Using OCR
By the PDFPUMA team · Published · 2 min read
Run the scan through OCR PDF. It recognises the text on each page and adds it as an invisible layer exactly over the words, so the pages look the same but you can search, select and copy. PDFPUMA does this in your browser in English, French, German, Spanish, Italian, Portuguese or Dutch.
What OCR actually does
A scanned page is a photograph of paper. Your PDF reader can display it, but it doesn't know there are words in it — so search finds nothing and you can't copy a sentence. Optical character recognition (OCR) looks at the image, works out the letters and words and where they sit, and stores that text in the PDF.
PDFPUMA keeps your original page images and places the recognised words invisibly on top, each one stretched to cover the word it came from. Searching highlights the right spot, and selecting text selects what you see.
Step by step
- Open OCR PDF and add the scanned PDF.
- Choose the document's language.
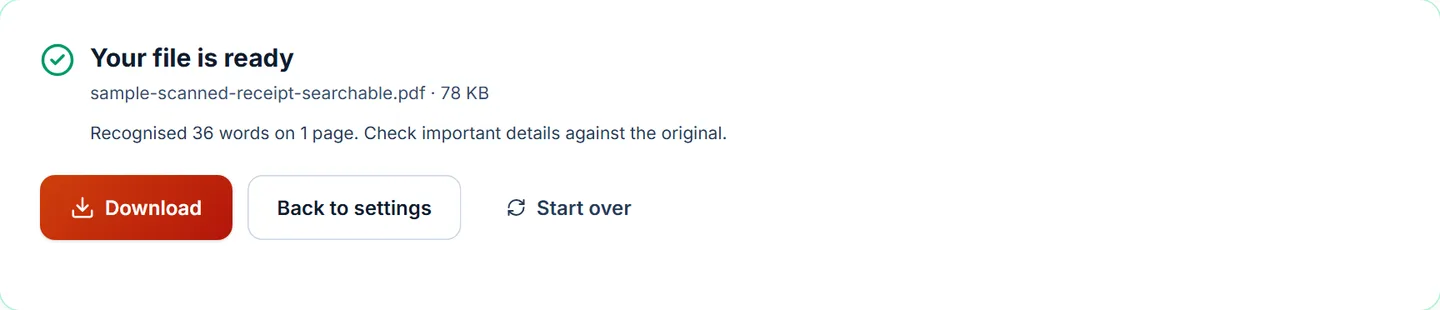
- Select Make searchable. Each page is rendered at 300 DPI and recognised; you can watch the progress and cancel at any time.
- Download the searchable PDF and try searching for a word you can see.
Pages that already contain real text are left alone, so a mixed document — some typed pages, some scans — is handled correctly.
Getting better results
- Scan at 300 DPI. Lower resolutions lose detail in small print.
- Keep pages straight and flat. Skewed or curled pages recognise poorly.
- Black and white or greyscale usually works as well as colour and makes smaller files.
- Check the uncertain-word count. PDFPUMA reports how many words were recognised with low confidence — check names, numbers and amounts against the original.
OCR isn't perfect. Handwriting, very small or decorative fonts, stamps over text and poor photos are recognised badly. Languages in other scripts — such as Chinese, Arabic or Cyrillic — aren't supported yet.
What to do with a searchable PDF
Once a scan has text you can split a batch into documents by their content with Smart split, compare two versions with Compare PDF, or search for and permanently remove personal details with Redact PDF.
Questions
Which plan includes OCR?
Business includes up to 200 pages per document and Agency up to 1,000. Every paid tool has a free demo on sample documents.
Is my scan uploaded for OCR?
No. PDFPUMA runs the open-source Tesseract engine in your browser; the language data is downloaded from pdfpuma.com, and your scan stays on your device.